
Table of Contents
Reflection AI is officially unveiling Beam, its first frontier, open-weight AI model. The Brooklyn-based startup developed the text-only system to handle reasoning, coding, and agentic tasks. The release aims to lower token costs and speed up inference for enterprise users.
Chinese developers currently dominate open-weight artificial intelligence with models like Z.ai’s GLM-5.2 and Qwen 3.8-Max. Beam represents the first U.S. startup model to demonstrate comparable performance against those Chinese systems. A direct analysis of Beam’s technical specifications reveals how the architecture achieves these performance metrics.
High Compute Training Powers Beam Architecture
Beam uses a mixture-of-experts architecture to execute complex tasks efficiently. This sparse routing design activates only a portion of the network for each forward pass. This strategic setup reduces processing demands without sacrificing output quality.
Beam features 501 billion total parameters across its neural network. It activates 23 billion active parameters during execution. In comparison, Z.ai’s GLM-5.2 contains 744 billion total parameters.
GLM-5.2 activates 40 billion parameters per forward pass. Activating fewer parameters lets Beam run with 3 to 4 times less inference compute. This design significantly cuts token costs for enterprise workloads.
Engineers pretrained the model on 23.8 trillion tokens from public and commercial sources. This pretraining dataset supports a 1 million-token context window. The team created custom filters for each programming language to eliminate low-quality code files.
Training began with a prototype model before scaling up to Beam Base. Developers built Beam Base using a cluster of 6,144 graphics cards. Base training completed in less than four weeks before midtraining extended system reasoning.
The final training phase utilized 10,000 GB300 graphics cards for reinforcement learning. This reinforcement stage ran for four weeks across virtual environments. The process launched 1.3 billion sandboxes to refine coding and agentic execution.
Custom management software recovered from 71 training errors during cluster execution. The software achieved a median recovery time of eight minutes per fault. This technical efficiency helped Reflection AI secure major hardware commitments and capital backing.
Securing Hardware and Challenging Global Rivals
Western AI developers face increasing pressure from both closed proprietary labs and open Chinese projects. Building competitive open-weight models requires massive capital investment and extensive compute capacity. Reflection AI combines large venture funding with hardware deals to challenge established industry rivals.
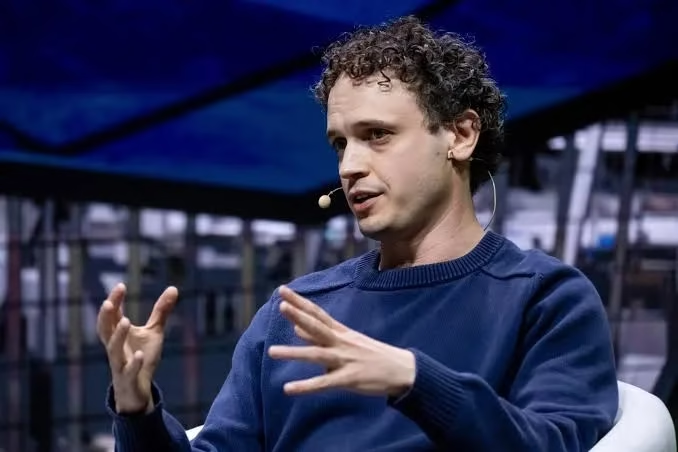
Former Google DeepMind researchers Misha Laskin and Ioannis Antonoglou founded the Brooklyn startup in 2024. The company raised $4.7 billion from Nvidia, Sequoia Capital, and Lightspeed Venture Partners. This investment valued Reflection AI at $25 billion.
Reflection AI secured compute access through 2029 by signing hardware agreements totaling over $7 billion. A $6.3 billion SpaceX deal provides Nvidia GB300 NVL72 appliances containing 72 GPUs each at Colossus 2. An additional $1 billion agreement with cloud provider Nebius further expands this infrastructure capacity.
Beam competes directly against U.S. open models like Nemotron and Inkling from Mira Murati’s Thinking Machines Lab. Benchmark results show Beam outscores Inkling on four shared coding tests, though Inkling offers multimodal capabilities. These hardware reserves directly support Reflection AI’s enterprise distribution and sovereign deployment strategy.
Deploying Customized Models for Enterprise Users
Public sector and corporate organizations increasingly select open-weight models to maintain complete control over sensitive data. Localized deployments help institutions prevent data leakage while managing long-term infrastructure expenses. Reflection AI addresses this demand by offering targeted local model customization services.
The firm sells an AI factory concept that lets clients train localized models on internal data. Nvidia CEO Jensen Huang publicly endorsed this concept to promote open artificial intelligence adoption across industries. Early partners testing sovereign factories include South Korea’s Shinsegae Group alongside major financial trading firms.
Reflection AI also established model supply agreements with the U.S. Department of Energy and the Department of War. CEO Misha Laskin and CTO Ioannis Antonoglou state open systems evolve faster and deliver stronger security. Institutional adoption now depends on the upcoming broad rollout and independent verification of performance claims.
Release Schedule and Unverified Benchmarks
Reflection AI is moving Beam from early access toward full commercial distribution across global networks. While early internal benchmarks indicate strong reasoning capability, external testing teams must still confirm these figures. The rollout strategy combines broad cloud availability with ongoing research into larger architecture designs.
Beam is currently available through an early access distribution program. Reflection AI plans to release model weights, technical documentation, and fine-tuning tools across cloud platforms later this month. The engineering team is already training its next, larger model as part of the product roadmap.
Third-party evaluators have not yet independently verified Beam’s performance benchmarks. Open-weight models also continue to trail top proprietary systems like Anthropic’s Claude Fable 5.1 on complex benchmarks.
Frequently Asked Questions About Beam
What is Beam?
Beam is a 501-billion-parameter open-weight AI model created by Reflection AI for reasoning, coding, and agentic tasks.
Who founded Reflection AI?
Former Google DeepMind researchers Misha Laskin and Ioannis Antonoglou founded Reflection AI in 2024.
How does Beam compare to Z.ai’s GLM-5.2?
Beam matches GLM-5.2 on advanced reasoning tests while utilizing between one-third and one-fourth the hardware during inference.