
Executive Summary
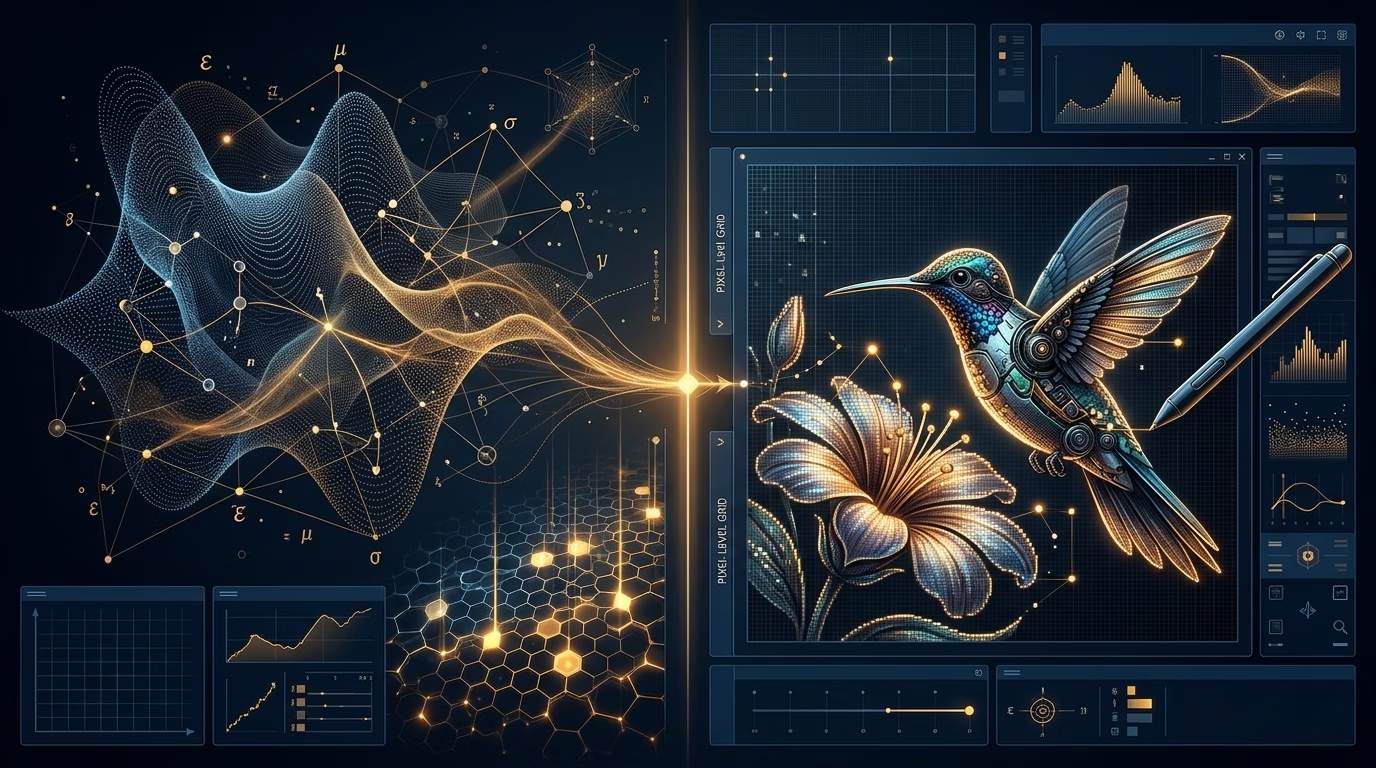
- PixelDiT2 Architecture. Researchers at the University of Rochester and NVIDIA created PixelDiT2, a diffusion transformer running in pixel space rather than latent space.
- Fixing AI Editing Flaws. By ditching compressed latent vectors, the model lets users adjust specific image details without altering unrelated background elements.
- Speed and Compute Parity. PixelDiT2 resolves the heavy compute penalty of earlier pixel diffusion models, matching the speed of top latent tools.
- Academic Recognition. The initial PixelDiT paper earned best paper finalist honors at CVPR 2026, with the PixelDiT2 paper set for NeurIPS 2026 this December.
- Targeting AI Video. The research team is expanding pixel space diffusion to video generation to eliminate temporal flickering and frame-to-frame drift.
Ask an AI image tool to fix a small detail, and it often ruins the rest of the picture.
Most modern tools, like ChatGPT and Google Gemini, use latent space diffusion models. These models compress images into compact math vectors. This trick saves compute power. It lets the tool create complex pictures in seconds. But it has a major drawback.
Because the model works in latent space, it cannot edit single pixels. When a user asks to change glasses or adjust hair color, the system redraws the whole picture. Unrelated parts shift, blur, or change completely.
Researchers at the University of Rochester and NVIDIA have solved this problem. Their team built PixelDiT2, a model that runs directly in pixel space. It gives users exact control over specific image zones without changing the rest of the artwork.
Table of Contents
The Problem with Latent Space Diffusion
Today’s text-to-image systems rely on latent diffusion. The model does not paint pixel by pixel. Instead, it works on a compressed sketch of the scene.
This setup makes rendering fast. But it limits fine control. Professor Jiebo Luo from the University of Rochester explains that users lose control because the model cannot tweak single pixels. Changing one small object forces the system to redraw surrounding areas.
For creative pros and game designers, this issue causes constant headaches. In fields like commercial production, where AI fashion models replace photo shoots, precise control over clothing cuts and fabric patterns is critical. Simple fixes currently turn into long prompt battles.
How PixelDiT Replaces Latent Space
To fix this flaw, Luo’s lab teamed up with NVIDIA researchers. They developed PixelDiT, a diffusion transformer that works directly on pixels.
The team shared their first model at the CVPR 2026 conference. The paper stood out among four thousand entries. Reviewers chose it as one of fifteen best paper finalists.
The first model proved that pixel-level editing was possible. Users could circle a small area, like a car door or a watch face, and change only those pixels. However, the first design needed heavy compute power.
Comparison Factsheet: Latent Space vs. PixelDiT2
The factsheet below details the architectural shifts between standard latent diffusion and the new PixelDiT family developed by Rochester and NVIDIA.
| Feature | Latent Space Diffusion | PixelDiT (v1) | PixelDiT2 (NeurIPS 2026) |
|---|---|---|---|
| Operating Domain | Compressed latent vectors | Raw pixel grids | Optimized pixel space |
| Local Detail Control | Poor (resamples entire canvas) | High (pixel-level editing) | Exact (pixel-level editing) |
| Compute and Speed | Fast generation speed | Heavy compute penalty | Matches latent model speed |
| Video Feasibility | Frequent frame-to-frame drift | Too heavy for multi-frame video | Core base for stable video |
PixelDiT2 Matches Speed While Adding Control
The research group has now revealed PixelDiT2. This updated model cuts the compute cost of raw pixel diffusion.
PixelDiT2 matches the quality and speed of top latent models. At the same time, it keeps full pixel-level control. Artists can adjust tiny details without changing the background, lighting, or face shapes.
The team will present PixelDiT2 at the NeurIPS conference this December. The project brought together PhD student Yongsheng Yu and NVIDIA researcher Wei Xiong, working alongside Professor Luo.
Expanding Pixel-Level Control to AI Video
With image editing solved, the team is tackling an even harder challenge: AI video.
Current AI video tools suffer from flickering and drifting details. Because latent models lack pixel control, objects shift shape from frame to frame. A character’s jacket might change color or buttons might vanish between cuts.
Video generation brings huge data demands, similar to the technical hurdles seen in DeepMind’s Genie 4 world simulation model. Models must ensure smooth motion across hundreds of frames. If pixel positions slip, the human eye spots the glitch right away.
The Rochester and NVIDIA team believes PixelDiT2 provides the right base for video. By running diffusion in pixel space, future video tools could let directors lock key objects in place across full scenes.
Explore Engineering Utilities and AI Solutions
Test payload formats, token calculations, and text transformations using our suite of Free Online Developer Tools.
Building custom computer vision models, fine-tuning diffusion pipelines, or developing video workflows? Consult with TeckScaler’s enterprise IT specialists →
Frequently Asked Questions
What is PixelDiT2?
PixelDiT2 is a diffusion transformer model built by the University of Rochester and NVIDIA that operates in raw pixel space rather than compressed latent space, enabling exact local image edits.
Why do latent space models struggle with fine editing?
Latent diffusion compresses visual details into mathematical representations. Because it does not operate on individual pixels, changing a small detail forces the model to redraw unrelated sections of the image.
How fast is PixelDiT2 compared to latent diffusion?
While early pixel diffusion was computationally heavy, PixelDiT2 achieves near-parity in generation speed and quality with top latent models while providing granular pixel control.
Can PixelDiT2 be used for AI video generation?
Yes. The research team is applying PixelDiT2 to video generation to eliminate temporal inconsistencies and let creators maintain stable objects across video frames.

[…] As commercial studios replace physical shoots, fine-grained control over clothing and textures remains essential. Discover how researchers are tackling this in our report on PixelDiT2 pixel-level AI image and video editing. […]